
Vector Databases & Embeddings for Context-Aware Legal AI Assistants
Vector databases & embeddings make legal AI smarter, reducing errors & improving context-aware research. Discover how they transform legal tech in 2025.
It’s 2025, and yet legal AI assistants still make mistakes that would make a first-year associate blush. Lawyers were promised intelligent AI companions that could streamline legal research, analyze case law, and even draft contracts with near-perfect accuracy. Instead, they got glorified search engines that return barely-relevant results, hallucinate legal citations, and confidently recommend maritime law in a tax dispute. The problem? Context.
Legal AI assistants, much like overeager interns, love regurgitating information without actually understanding what they’re saying. They rely on keyword-based retrieval methods that fail spectacularly when nuance, precedent, and jurisdiction come into play. Fortunately, a properly built vector database for legal AI provides a way to turn these AI assistants from glorified chatbots into actual, context-aware legal tools. Pairing that retrieval layer with a short-lived, auto-expiring cache in front of it is exactly what ephemeral memory stores add — context without a permanent shadow record.
Why Legal AI Assistants Fail Without Context (And How Vectors Fix That)
The "Context-Free" Legal AI Disaster
If you’ve ever used an AI-powered legal research tool and thought, Wow, this is just Google with a law degree from the back of a cereal box, you’re not alone. Most AI assistants rely on basic keyword matching, which means they look at what you type and then scramble to find documents that contain those words—without considering whether those documents are actually relevant.
Ask a traditional AI system about "reasonable expectation of privacy," and it might pull cases from criminal law, employment disputes, and even landlord-tenant litigation, completely ignoring the legal domain you’re actually working in. This is because traditional AI models don’t understand the semantic relationship between terms. Instead, they just play a legal word association game—often with disastrous results.
How Vector Embeddings Actually Work (For Those Who Don’t Just Copy-Paste from GPT Docs)
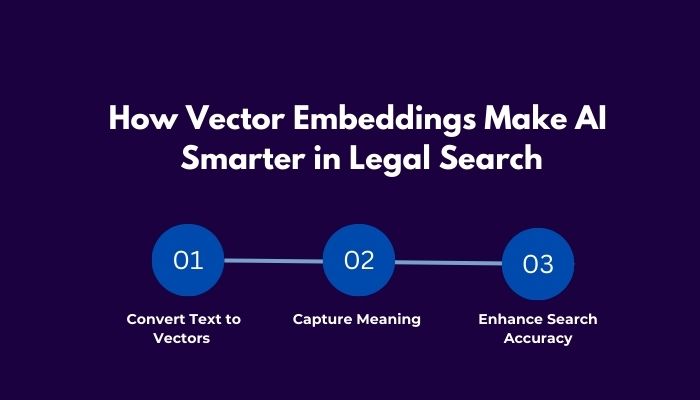
This is where vector embeddings step in to save the day. Unlike keyword-based systems, embeddings convert words, phrases, and entire legal texts into dense numerical representations—also known as vectors. These vectors capture meaning, not just words. Fitting an entirely new representation type like an embedding column into a data model built for twenty-character text fields is the exact problem automated schema evolution in long-lived legal AI systems is designed to solve.
For example, OpenAI embeddings, BERT, and other models generate high-dimensional vector representations of text. Words with similar meanings have similar vectors. This means that instead of just matching "reasonable expectation of privacy" word-for-word, an AI using embeddings understands that the phrase refers to a constitutional principle tied to the Fourth Amendment rather than something a landlord writes in an eviction notice.
The best part? Legal AI embeddings allow AI systems to perform semantic search for law firms—meaning they retrieve documents based on meaning, not just exact wording. This is why embeddings are a game-changer for legal AI: they enable context-aware results, not keyword-matching disasters.
Vector Databases: The Legal AI's Secret Weapon
What the Hell is a Vector Database and Why Should Lawyers Care?
If embeddings are the key to legal AI understanding, vector databases are the vaults where this knowledge is stored and efficiently retrieved. Unlike traditional relational databases (which are great for structured data but terrible for high-dimensional vectors), a vector database for legal AI is specifically designed to store and search legal document embeddings at scale.
Here’s why this matters: When a legal AI assistant needs to retrieve relevant case law, it doesn’t just scan for matching words. Instead, it compares the vector representation of the query against a database of precomputed legal embeddings. This allows the AI to return results based on actual legal relevance rather than keyword occurrence.
Top Vector Databases for Legal AI (And Why Not All Are Created Equal)
So, which vector databases are worth your time? Right now, Pinecone, Weaviate, FAISS, and Chroma are leading the pack. Each has its own quirks:
- Pinecone is fast, scalable, and great for real-time AI applications, making it a favorite for cutting-edge legal AI startups.
- Weaviate is an open-source vector database that integrates well with knowledge graphs, which is useful for AI models that need structured legal data.
- FAISS (by Facebook, because of course) is powerful but requires serious engineering effort to scale properly.
- Chroma is lightweight and great for smaller-scale AI models, but don’t expect it to handle millions of legal documents efficiently.
Choosing the wrong database is like hiring a tax attorney to handle a murder trial—technically possible, but a terrible idea.
Context-Aware Legal AI: The Good, The Bad, and The Infuriating
Embeddings for Precedent Search (Aka: AI That Doesn’t Suggest Maritime Law for a DUI Case)
Precedent search is where AI should shine, yet most legal AI tools fail miserably. By using embeddings, AI can compare the contextual meaning of past cases rather than just searching for similar words.
Imagine searching for "corporate veil piercing" in case law. A traditional keyword-based search would return every case that mentions "corporate veil," regardless of whether it discusses actually piercing it. A system powered by embeddings, on the other hand, understands that you’re looking for cases where courts held business owners personally liable—not just any case where the phrase appears.
Contracts, Summarization, and the Myth of "AI Reads Contracts So You Don’t Have To"
AI-powered contract review is another area where embeddings make a difference. They enable AI to detect hidden risks and obligations without getting distracted by irrelevant boilerplate language.
That said, let’s be clear: AI does not replace human lawyers. While embeddings help AI understand legal concepts more effectively, you still need a trained legal mind to interpret the results. If you blindly trust AI to review a contract, don’t be surprised when you end up accidentally signing away all of your firm’s assets in a "minor clause" the AI missed.
Implementation Nightmares: Scaling Legal AI with Vectors
The Fine Print of Scaling (And How Law Firms Will Mess It Up Anyway)
Scaling vector-based AI systems as part of a broader AI-powered legal research infrastructure isn’t as easy as plugging in an API and calling it a day. Law firms dealing with millions of legal documents will face storage and query speed issues that require careful engineering. Even worse, AI-powered legal systems need regular updates to incorporate new case law and statutes. If your embeddings are outdated, your AI will start serving up bad legal advice—kind of like a lawyer who hasn’t read a new statute since law school.
Ethical and Security Landmines (Because the Bar Association Likes to Ruin Fun Things)
As if performance challenges weren’t enough, legal AI systems also need to comply with strict data security laws. Embeddings, for all their brilliance, can sometimes memorize sensitive data—which is a privacy and compliance nightmare.
Law firms deploying vector-based AI need to ask:
- Are the embeddings storing confidential client information?
- How do they handle attorney-client privilege in AI-assisted legal work?
- Will the ABA ever catch up and provide clear regulations on AI use? (Spoiler: probably not soon enough.)
AI That Doesn’t Give You Terrible Legal Advice
Will AI Replace Lawyers? No, But It Will Make You Work Faster
Vector embeddings and databases won’t replace lawyers, but they will make legal research, precedent analysis, and contract review significantly more efficient. The biggest losers? Overpriced associates who charge $500/hour to Google case law.
Beyond Vector Databases: What’s Next for Legal AI?
The next step in legal AI will involve retrieval-augmented generation (RAG)—a fancy way of saying "AI that retrieves the right documents before trying to answer your question"—and fine-tuning models on firm-specific data to avoid hallucinated legal nonsense.
Yes, Legal AI Can Actually Be Useful
The bottom line? Vector databases and embeddings finally make legal AI actually usable. Just don’t expect them to replace human lawyers anytime soon. At least, not competent ones.
When a matter's documents outgrow a single context window, our guide to context window recycling for long-form legal memory covers how to keep the model's memory intact anyway.
Once those vectors are retrieved, an agent still needs somewhere stable to hold them for the rest of a session — persistent memory slots in stateful legal agents covers exactly that layer.
Those embeddings are most useful when they're queried with a narrow, well-formed question rather than a sprawling one — intelligent query decomposition for complex legal research covers how to get from a messy client question to that narrower form.
Vector search only helps if the underlying passages were embedded with the right fact pattern in mind — embedding fact patterns for semantic alignment in legal RAG covers how to get that alignment right.
Put a legal AI workflow to work — the right way.
Talk through the workflow you want to automate — contract review, drafting, or document intelligence — with a team that ships secure AI for law firms.